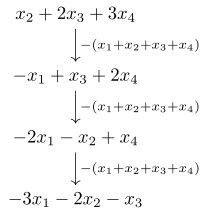3 The Green–Tao Theorem
Theorem 3.1.
For all ,
the primes contain an arithmetic progression of length
.
Theorem 3.2 (Weighted Szemerédi).
For all
and , there
exists such that
for any function
satisfying ,
|
|
where is a quantity
that goes to as
at a rate that
depending on
and .
There is a standard method that allows converting between a statement like the above about
into a statement
about : given a subset
of , just view it as a
subset of (arithmetic
progressions in that lie
in correspond to genuine
arithmetic progressions in ).
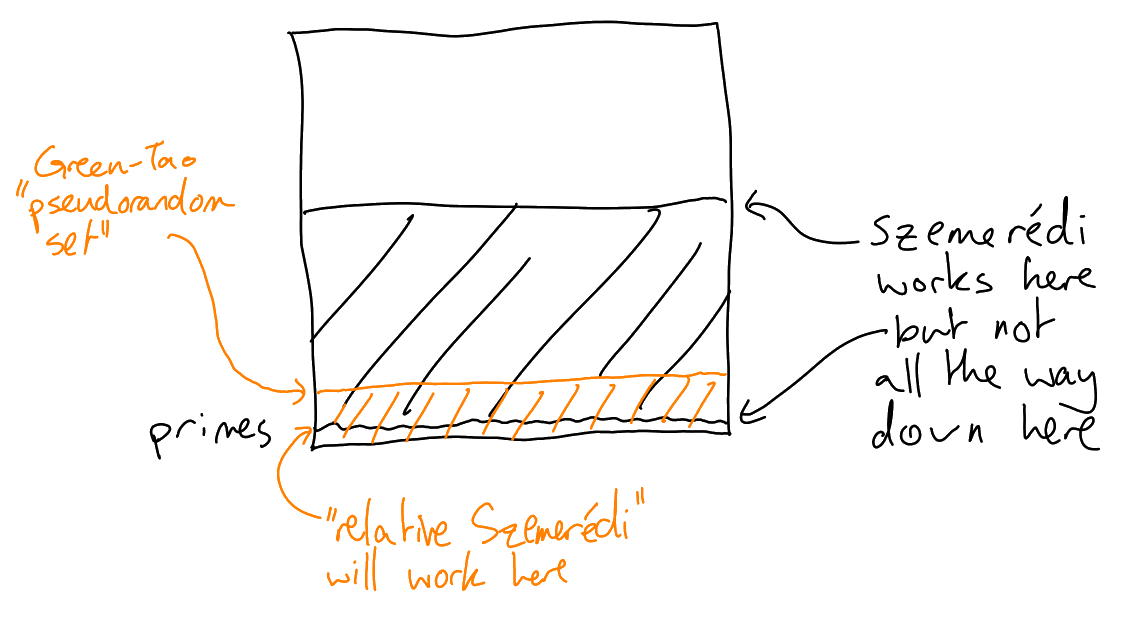
Insight of Green and Tao: the primes are dense in a certain subset of the naturals.
We will use some results of Conlon–Fox–Zhao which are sparse versions of the hypergraph regularity results
we saw earlier. We will only prove one of these results in lectures, which is the sparse counting
lemma.
Definition 3.3.
A function
is said to satisfy the -linear
forms condition (-LFC)
if
|
|
for any choice of exponents .
Example 3.4.
We will omit writing out the
in this example.
satisfies the
-LFC if
|
|
satisfies the
-LFC if
|
|
relates to three term progressions: it is the arithmetic progression
for
.
Theorem 3.5 (Relative Szemerédi).
Let
and and suppose
satisfies the
-LFC. Suppose
is sufficiently large
and coprime to .
Let satisfies
for all
and
suppose .
Then
|
|
where is as in Theorem 3.2.
Often refer to as a
pseudorandom majorant for .
Note: taking
here to be the indicator of the primes won’t satisfy the conditions above, because we need
. Instead, we’ll use the
fact that is not bounded
(takes values in ).
Think of “𝟙.”
In the original Green–Tao proof, they needed an additional condition as well as the
-LFC,
and this additional requires a lot of analytic number theory to prove. One of the great contributions of the
proof by Conlon–Fox–Zhao was to remove this additional condition, and in particular greatly reducing the
amount of analytic number theory needed to prove the result.
Consider the van Mangoldt function
|
|
By the Prime Number Theorem,
(Remark: we won’t need the Prime Number Theorem to prove Green–Tao)
Problem: is biased with respect
to small residue classes. Use -trick:
let be a
function
with e.g.
. Let
, and consider
only primes ,
by defining
|
|
where is the Euler totient
function. Can show ,
provided
grows sufficiently slowly.
Reminder: instead of ,
want to consider
|
|
Proposition 3.6 (Pseudorandom majorant for the primes).
For all
, there exists
such that for all
sufficiently large ,
there exists
satisfying the -LFC
and for
all .
is given
by
|
|
where
-
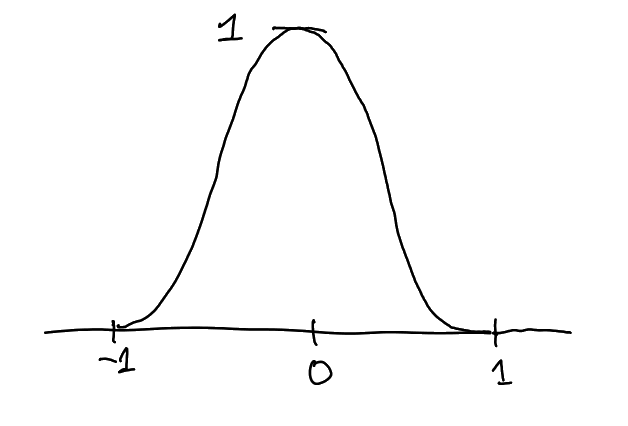
is a smooth function
supported on
with
-
-
.
-
.
Compare with
and .
Next goal: “Approximate”
by with
(transference principle).
Definition 3.7.
Let be an abelian
group (which you can think of as being ),
let , and let
a surjective
homomorphism, .
We say is an
-discrepancy pair
(DP) with respect to
if
|
|
for all functions .
In words: no function in fewer variables can distinguish
from
.
Can think of .
Theorem 3.8 (Dense Model Theorem).
For all
, there
exists and
such that the
following holds: Let be
a finite set, let be a
collection of functions .
Suppose
satisfying
|
|
and
satisfies
and . Then
there exists
such that
and for
all .
Corollary 3.9.
For all ,
there exists such that
the following holds: Let
be an abelian group, ,
a surjective
homomorphism. Let
be such that ,
and
is an
-discrepancy pair
with respect to .
Then there exists
such that
and is an
-discrepancy pair
with respect to .
Deduction from Theorem 3.8.
For any collection of functions
, define a generalized
convolution with respect to
:
|
|
So indeed the earlier expression looks like a reasonable definition for a generalised convolution.
Notice that the LHS in ?? 30 is just .
Let be
the set of functions which can be written as convex combinations of generalised convolutions with respect to
. Then by the
hypotheses, is an
-discrepancy pair with
respect to , which
is equivalent to
for all .
Want:
for all .
So it suffices to show that
is closed under multiplication. Indeed,
Define a norm on functions
by
|
|
This has a dual:
By definition, .
Note
|
|
and by duality
Lemma 3.10.
The unit ball of
is just .
We will use Hahn–Banach to prove this.
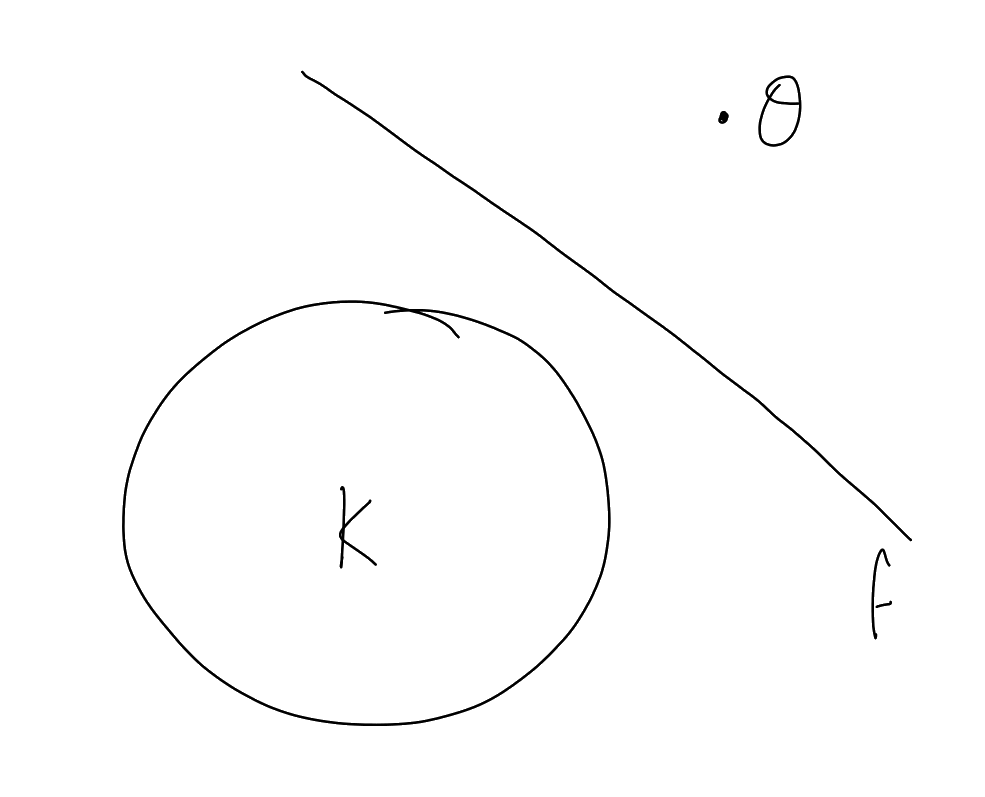
Theorem 3.11 (Hahn–Banach).
Let
be a closed convex body in ,
and suppose .
Then there exists
such that
while .
Proof.
Suppose .
Then
So
is in the unit ball of .
Convex combinations of elements in
are also in the unit ball by the triangle inequality.
For the converse, we need Hahn–Banach. Suppose
. By Theorem 3.11,
there exists
such that but
. The latter
implies .
But
Hence
does not lie in the unit ball of .
□
This implies that the unit ball of is
closed under multiplication. Hence, ,
then
|
|
(dual norm is submultiplicative).
Theorem 3.12 (Dense Model (Theorem 3.7’)).
For all
, if
satisfying
and
satisfies
, then there
exists such
that .
Proof.
Given ,
,
it suffices to show that there exists
with ,
assuming that
for some sufficiently small .
Suppose that there is no such ,
i.e. cannot be
written as ,
with
|
|
In other words: we are supposing that .
Note that
and
are both convex bodies, and both contain .
Thus
is convex and contains
and .
By Hahn–Banach, there exists
such that
and .
Taking 𝟙,
we note that
|
𝟙 |
where .
Thus .
On the other hand, if ,
so
for all
with .
So .
So far, we have
|
|
So if we had
bounded above, we would be done. Indeed, by Weierstrass approximation, there exists a polynomial
such
that
|
|
Recall that earlier we used duality to show ,
which is why we only need the polynomial approximation to hold in the interval .
Let . We can
do this with .
Now
|
|
and
|
|
Choosing
such that ,
we arrive at a contradiction. □
.
means
.
. (for all
)
Work with -partite
-uniform
weighted hypergraphs.
with each . For two
such hypergraphs,
and ,
write
whenever
for all
and all .
Given a weighted -uniform
hypergraph
on ,
define
|
𝟙 |
Given a weighted -partite
-uniform
hypergraph on ,
define
|
|
Definition 3.13.
Say that a -partite
-uniform weighted
hypergraph
satisfies the -LFC
if
|
|
Our definition can be recovered by making the substitution
|
|
Theorem 3.14 (Sparse counting lemma).
Let
be weighted hypergraphs on .
Suppose that satisfies
the -LFC (as in
Definition 3.13), ,
, and
. Then
|
|
The proof consists of the following steps:
(1)
Lemma 3.15 (Telescoping argument).
Let ,
and ,
. If
, then
|
|
Sketch proof.
Now we no longer have to worry about .
Then repeat. □
(2)
Lemma 3.16 (Strong linear forms).
Suppose
satisfies the -LFC as defined in
Definition 3.13 and suppose ,
. Then
|
|
where
and is
either
or .
Sketch proof.
Use LFC and Cauchy-Schwarz. □
(3) Next (final) lecture: densification strategy
At each step, if
and , find
such
that .
Sketch proof of Theorem 3.5.
Given
and ,
, satisfying
the -LFC:
Define the weighted hypergraphs
on :
and from the Dense Model Theorem, obtain
such that ,
with corresponding weighted hypergraph
|
|
By the sparse counting lemma, we have
Corollary 3.17.
For all ,
there exists such that
the following holds: Let
with ,
and
. Then
|
|
But also, by Corollary 3.9, ,
so by the weighted Szemerédi Theorem we get the result. □
Proof of Theorem 3.14.
By inductionon .
and
straightforward.
Suppose true for , and
consider . Without loss
of generality is not
identically . Define auxiliary
weighted hypergraphs
by
Note that these do not depend on ,
,
. Also
define
and .
Observe that by the LFC,
and by Cauchy–Schwarz,
(i).
Claim: .
Proof of claim: Since
(ii). For any ,
,
,
𝟙𝟙𝟙𝟙𝟙𝟙
Note that involves at most
unbounded functions,
so the second term is
by the inductive hypothesis. □
Consider
Since , the second
term is at most .
The first term, by Cauchy–Schwarz, is bounded above by
|
|
By the strong linear forms condition, may replace
by . So
.
Expand
|
|
So the first term is bounded above by
by LFC.
Notice that
|
|
and each term is, up to ,
equal to .
Indeed (let’s do the hardest term),
|
|
but by
the claim, so done by inductive hypothesis. □
Ω