8 Invariance principles
Example.
Let
uniform on ,
.
Then .
Here,
is meant to mean “has approximately the same distribution as”.
Here, we saw that replacing
by another variable
with roughly similar properties (e.g. same mean and variance) didn’t affect the distribution of the sum
by much.
How can we define “approximately same distribution”? You may have seen before that we can define it as
holding for all
. This can be
rephrased in terms of 𝟙.
We will instead use a notion of similar distribution where we use continuous functions (in fact we will even
require stronger conditions than this).
Theorem 8.1 (Generalisation / modification of the Berry–Esseen Theorem).
Let
and
be sequences of independent
random variables. Suppose that
and for
each . Let
be such
that
(bounded third derivative). Then
|
|
Note.
For ,
we have
and
(will be an exercise on the example sheet).
Proof.
By the triangle inequality, the quantity we wish to bound is at most
|
|
Write
for . So
the above is
|
|
By Taylor’s Theorem,
where
is between
and ,
is between
and
.
Taking expectations and subtracting, and using the fact that
and
and also
that
and are
independent of ,
we get
|
|
which has size at most .
Summing gives the result. □
Corollary 8.2.
Let
be independent with
and with
. Let
be such
that .
Then
|
|
where .
Proof.
Let be normal
with mean zero and .
Then .
By the previous theorem, we get a bound of
|
|
Definition 8.3.
Let be
a multilinear function .
Alternatively, think of
as a formal multilinear polynomial. Define
-
,
-
,
-
,
-
,
-
,
-
.
Note that
and do not
depend on
and also that ,
and .
Define
One could also define ,
.
Now let be independent
random variables with ,
. Then
define to be
evaluated
at , i.e.
. Then it is easy
to check that ,
. For
example,
Also, defining
to be we
have that .
Suppose that
are independent and
|
|
Then the proof of Bonami’s Lemma straightforwardly gives that if
has degree
at most ,
then .
Theorem 8.4 (Invariance principle).
Let
and be sequences of random
variables satisfying condition ().
Let be a multilinear
polynomial of degree at most
and let
satisfy that
(bounded fourth derivative). Then
|
|
Remark.
It is possible to get a stronger result than this, but we prove this version because it can be proved
with the version of Bonami’s Lemma mentioned above.
Example.
Examples of
where the LHS of the above Theorem is large if we set
,
:
-
.
Then the distribution of
is then uniform on ,
so LHS is large. The RHS is large because
is large.
-
.
Again, distribution of
is uniform on .
The RHS is large because
is large, and also because all
terms are large.
Proof.
By the triangle inequality, the quantity we wish to bound is at most
|
|
Write .
Then we can rewrite each summand as
|
|
Let ,
. So we
can rewrite as
|
|
But
|
|
and
|
|
Taking expectations and subtracting, noting condition
()
and
that
and are
independent of
and , we
see that everything cancels apart from the error terms, so we get
|
|
But
|
|
But
satisfies ()
and
has degree at most .
So Bonami’s Lemma applies, and we get an upper bound of .
Same for ,
so summing over
gives the result. □
Gaussian Space
Let . We say
that ,
is
-correlated
with if
, where
. If
and
, thene there are
independent Gaussians ,
with
,
, so
and
.
A nice way to construct a pair
of -correlated Gaussians
is to take unit vectors ,
and set
,
, choosing
so that
. Writing
, we
have
|
|
Definition 8.5.
Let
and let .
Then .
Remark.
If
and , then
and
, from which it
follows that is
self-adjoint. If and
, then there are
independent Gaussians ,
with
,
. But
, so
. From this, it
follows easily that ,
i.e.
forms a semigroup, called the Orstein–Uhlenbeck semigroup.
We define, if ,
to be
Theorem 8.6 (Sheppard’s formula).
Let
be a half space, i.e. a set of the form
for some non-zero .
Then 𝟙.
Proof.
We are interested in
|
𝟙𝟙 |
Without loss of generality
is a unit vector. Then
and
are -correlated
-dimensional
Gaussians (by rotational invariance, we can think of
as just being ).
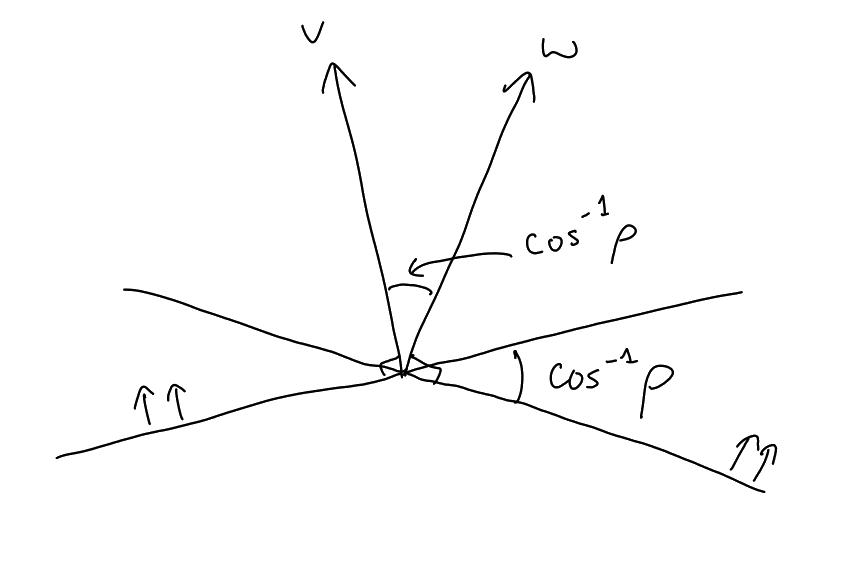
So pick unit vectors ,
with , and
consider ,
,
. Then
draw a picture:
From this we get
|
|
Definition 8.7 (Rotation sensitivity).
Let .
The rotation sensitivity
is
|
𝟙𝟙 |
If is balanced (i.e. has
Gaussian measure ),
then , so
|
𝟙𝟙𝟙𝟙𝟙 |
The statement 𝟙
is equivalent to .
Lemma 8.8 (Subadditivity of ).
Let be a
balanced set in .
Then for any
we have
|
|
Proof.
For ,
let . Let
and
be independent
-dimensional
Gaussians and let
for each .
Then
and are
-correlated,
so
|
𝟙𝟙 |
Also,
and
are ()-correlated.
So the RHS equals 𝟙𝟙.
The result now follows from a union bound. □
Corollary 8.9 (Special case of Borell’s isoperimetric inequality).
Let
be balanced
and let .
Then .
Proof.
because -correlated
variables are independent. Setting ,
we deduce that ,
hence .
□
Ω